
From "usable" to "useful"
Large models entered production for text generation, code assistance and Q&A.
Cloud Infrastructure
AI Infrastructure
By Industry
Resources & Support
AI Token Factory Solution
EasyStack AI Token Factory is a production-grade solution built on ECF (Cloud Infrastructure) and EAF (AI Infrastructure). It transforms GPU, NPU and DCU capacity into OpenAI-compatible token APIs with unified compute governance, model lifecycle management, intelligent routing, token metering, chargeback and enterprise-grade security.
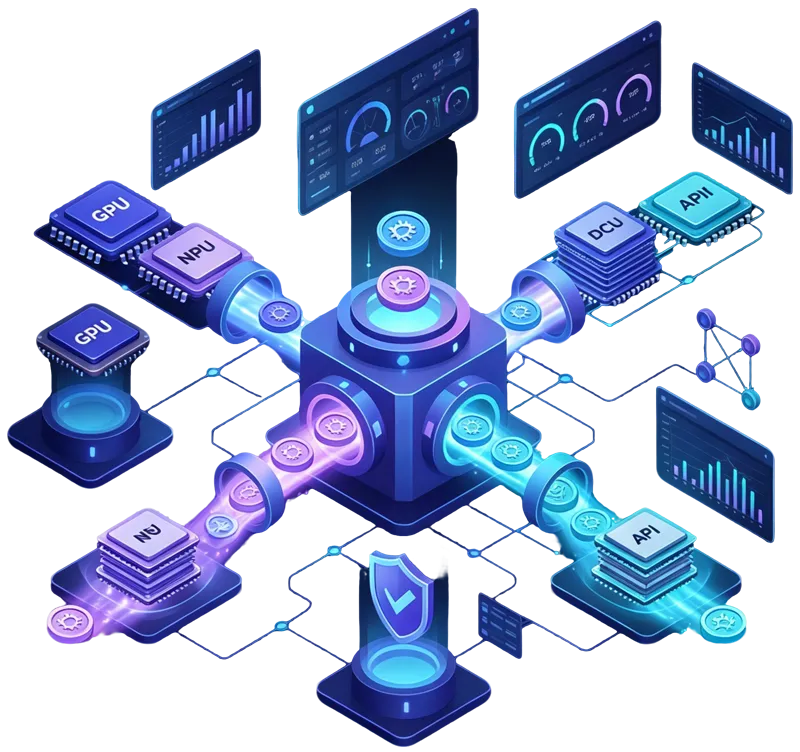
AI is moving from experimentation to industrialization. As inference workloads are projected to exceed 70% of AI compute demand by 2028, enterprises and service providers need a way to turn heterogeneous AI infrastructure into standardized, governable and monetizable token services.
Large models are no longer the end product — they are the engine. The real output is tokens: the unit of AI consumption, cost, governance and business value. The AI Token Factory combines ECF for cloud foundation, EAF for heterogeneous AI compute and MaaS, and a dedicated Token Service Layer for API gateway, metering, billing and governance.
An open, hardware-agnostic, sovereign-ready AI token factory that lets every enterprise or cloud provider produce, control and monetize AI tokens at scale.
Produce standardized, OpenAI-compatible token services from private AI infrastructure.
Improve accelerator utilization from ~25% to 70–80% with pooling and intelligent scheduling.
Deliver model-to-API services quickly with pre-configured engines and one-click deployment.
Maintain data sovereignty, compliance and full auditability with multi-tenant isolation.
AI application evolution has moved through three phases, each raising the bar for infrastructure.
Large models entered production for text generation, code assistance and Q&A.
RAG, fine-tuning and prompt engineering adapted models to vertical scenarios.
AI Agents perform complex tasks, call tools and invoke models repeatedly — creating bursty, non-deterministic inference demand.
Coarse allocation and isolated workloads leave accelerators underused.
Separate systems for compute, inference, gateway and applications.
NVIDIA GPU, Hygon DCU, Ascend NPU and others require unified management.
Token consumption is not tracked by user, project, department or model.
Public AI services create data leakage, compliance and lock-in concerns.
Compute governance, model service, a dedicated token layer and an AI application platform — open, hardware-agnostic and sovereign-ready.
Unified management, scheduling and observability of heterogeneous AI accelerators.
Model lifecycle, inference engines, deployment and unified gateway.
OpenAI-compatible API, intelligent routing, token metering, billing and quota.
RAG, Open WebUI, Agent templates and one-click deployment.
What the AI Token Factory delivers
Unified infrastructure for NVIDIA GPU, Hygon DCU and emerging accelerators with PXE auto-discovery.
NVIDIA MIG hardware profiles plus HAMI software compute/VRAM sharing; DCU and NPU passthrough.
Binpack, Spread and topology-aware strategies avoid cross-NUMA/PCIe performance loss.
vLLM, SGLang and Llama.cpp pre-configured for online, reasoning and edge workloads.
OpenAI-compatible API with intelligent routing, fallback and fine-grained rate limiting.
Input/output usage by API key, user, project, department and model with report export.
RBAC, namespace isolation, quota management and audit logs retained ≥180 days.
Versioned application templates with one-click deployment in under 10 minutes.
Measured outcomes across compute, delivery speed, cost visibility and revenue.
Four building blocks cover the full path from raw AI compute to a billable token service.
One cloud, multi-accelerator infrastructure with automatic discovery and unified governance.
Fine-grained accelerator sharing plus intelligent placement for every workload profile.
Full model lifecycle behind a single OpenAI-compatible, intelligently routed gateway.
Turn AI infrastructure from a cost center into a measurable, monetizable service.
Governance and security controls keep every token inside your jurisdiction.
Models and data stay on-premises; input/output tokens never leave the private domain.
Namespace, MIG hardware, Kata sandbox and network/storage/compute isolation.
RBAC fine-grained control; audit logs ≥180 days with masked API keys.
Regular image scanning; high-risk repairs completed within 7 days.
99.9% control-plane availability; multi-replica inference with RTO <60 s.
A neutral, on-premises alternative to cloud AI platforms and inference services.
Explore how organizations across industries produce, govern and monetize AI tokens.
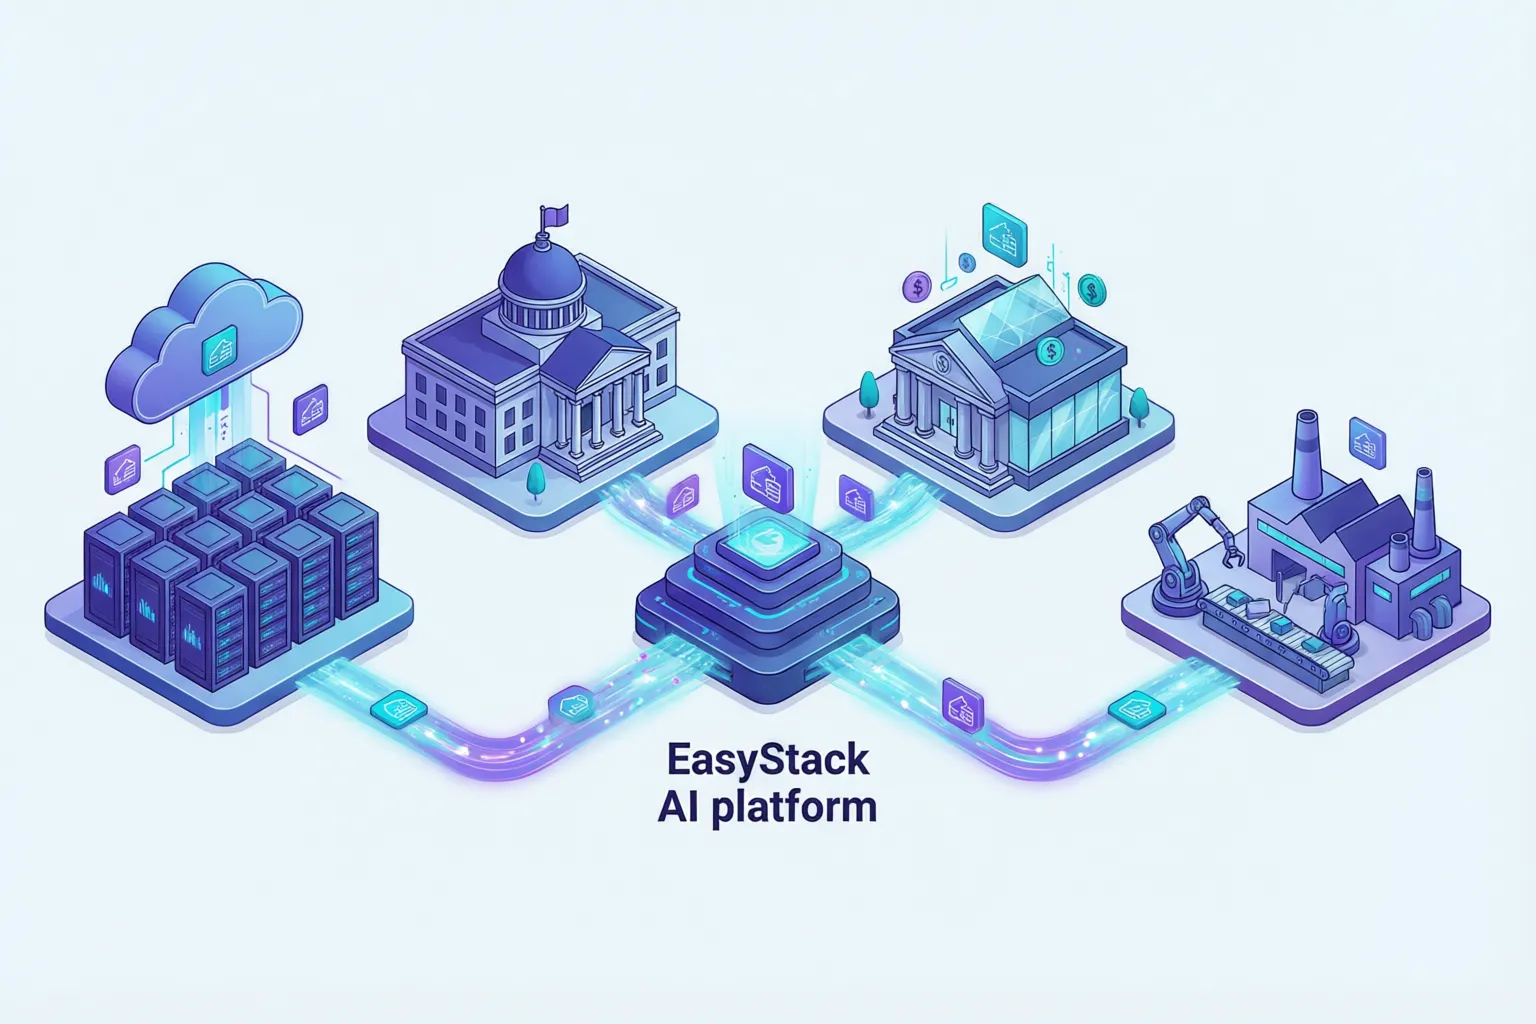
A regional hosting provider deploys ECF + EAF to offer OpenAI-compatible token APIs to SMEs. Token metering enables usage-based billing while multi-tenant isolation protects customer workloads.
A provincial government builds a private token factory on Hygon DCU and NVIDIA GPU. Citizen Q&A and policy interpretation run with response latency under 300 ms, and all data remains within national borders.
A national bank deploys DeepSeek as an internal API service for investment advisory, compliance review and customer service. Token usage is tracked by department for cost allocation, improving service efficiency by 60%.
A large manufacturer uses RAG and AI Agents for equipment fault diagnosis and maintenance planning, reducing fault handling time by 40%.
Talk to our solution architects about turning heterogeneous AI infrastructure into standardized, governable and monetizable token services — or download the full solution whitepaper.